Accelerate Your Intelligence at Scale
DELAWARE-BASED CLOUD COMPUTE

Accelerate Your Intelligence at Scale

High-performance GPU credits designed for researchers pushing the boundaries of AI and machine learning.

Deploy NVIDIA H100 and A100 instances in seconds. Designed for researchers who need raw performance and 99.9% uptime without the enterprise overhead.

Enterprise-Grade Performance

Scalable Compute for the AI Frontier

Provision high-performance GPU clusters in seconds. Designed by researchers, for researchers, with the lowest latency and highest throughput in the industry.

NVIDIA H100 Hopper Instances
The Gold Standard

NVIDIA H100 Hopper Instances

Starting at $2.10/hr per GPU

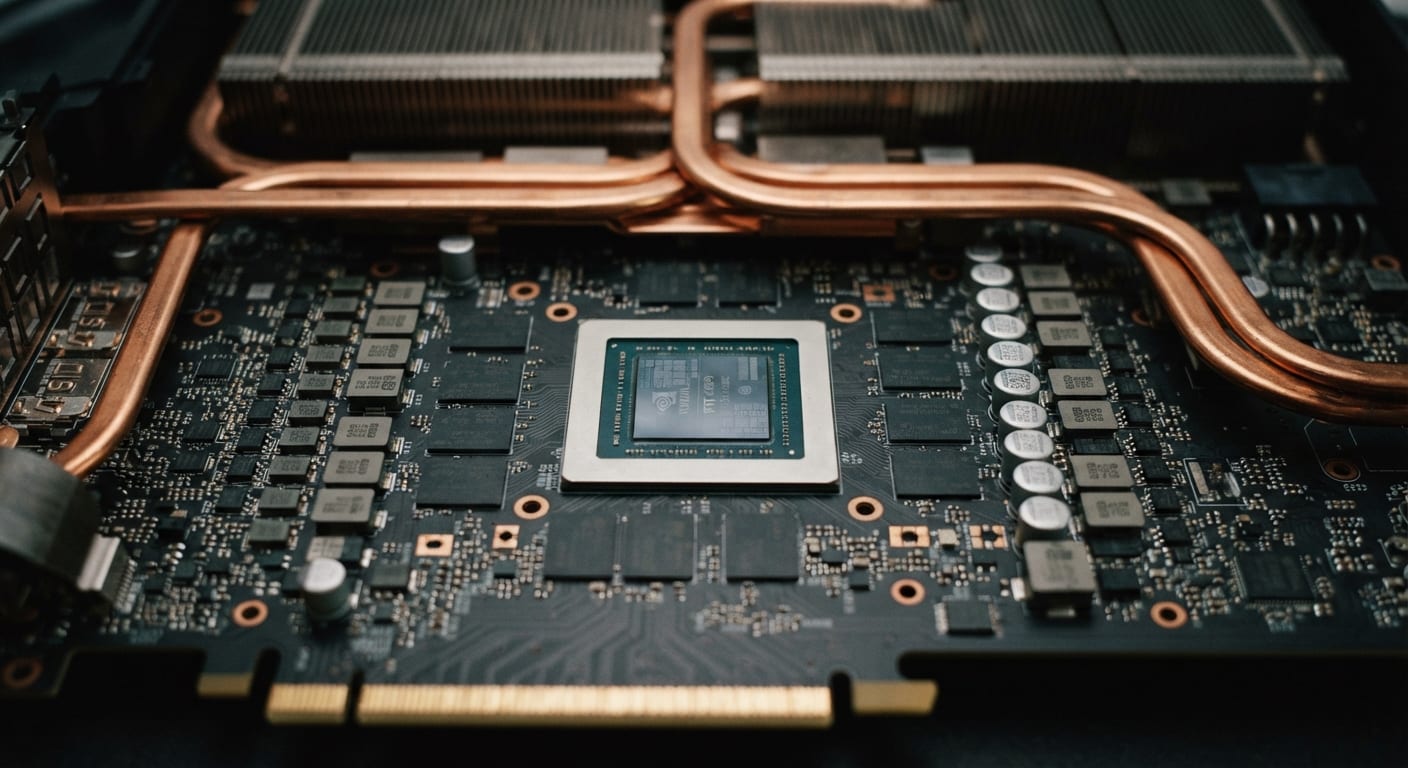
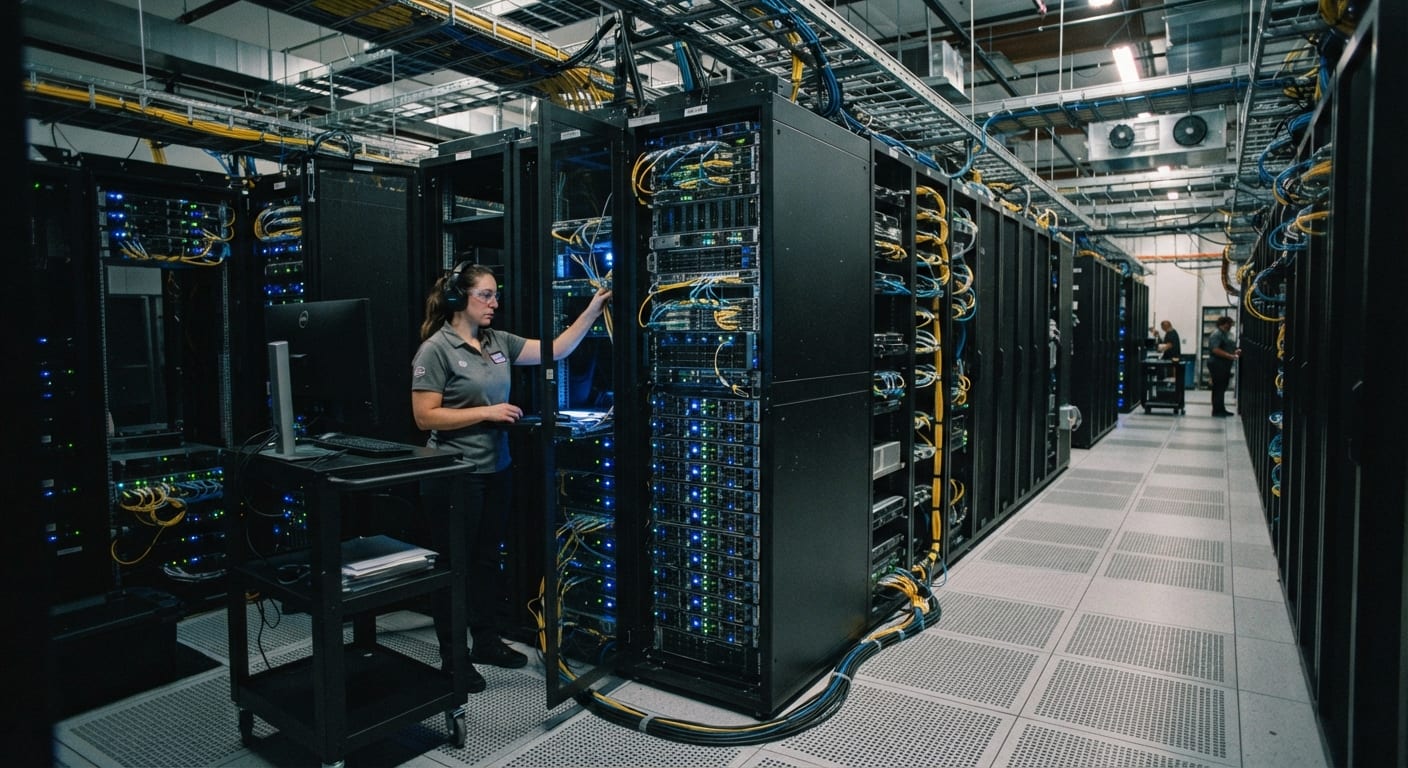
Accelerate your most demanding LLM training and inference workloads with the world's most advanced GPU. Our H100 clusters feature 80GB HBM3 memory and ultra-fast SXM5 interconnects for seamless multi-node scaling.
NVIDIA A100 Tensor Core Clusters
High Throughput

NVIDIA A100 Tensor Core Clusters

Optimized for Deep Learning

The industry standard for data science and AI research. IPX GPU offers dedicated A100 instances with 80GB VRAM, providing the memory bandwidth required for large-scale computer vision and NLP model fine-tuning.

RTX 4090 Compute Nodes
Prototyping Power

RTX 4090 Compute Nodes

High-Performance, Low-Cost

Ideal for researchers needing raw power on a budget. Our 4090 instances provide 24GB of VRAM and Ada Lovelace architecture, making them the perfect choice for rapid experimentation and local-scale model testing.

Prepaid Compute Credits
Flexible Billing

Prepaid Compute Credits

Unlock Volume Discounts

Simplify your research budget with our transparent credit system. Purchase bulk compute credits to unlock specialized volume discounts and manage multiple research teams under a single, unified Wilmington-based billing dashboard.

TRUSTED BY INNOVATORS

Powering the Next Generation of AI

Discover why leading ML researchers and engineering teams rely on IPX GPU for high-performance compute and seamless scalability.

Seamless scalability for LLM training
SCALABILITY

Seamless scalability for LLM training

Dr. Aris Thorne, Lead AI Researcher

IPX GPU's H100 clusters provided the raw computational power we needed to shave weeks off our large language model training schedule. The credit-based system is refreshingly transparent, making it easy to manage our lab's budget without worrying about hidden egress fees.

The most reliable uptime in the valley
RELIABILITY

The most reliable uptime in the valley

Marcus Chen, CTO at NeuralPath

We migrated our entire computer vision pipeline to IPX GPU and immediately saw a 30% reduction in inference latency. Their Delaware-based infrastructure is rock-solid, ensuring our production-grade AI applications never skip a beat during peak demand.

Unmatched price-to-performance ratio
EFFICIENCY

Unmatched price-to-performance ratio

Sarah Jenkins, Independent ML Engineer

As an independent researcher, I need every compute credit to count; IPX GPU offers the most competitive rates on A100s I have found in the US. The instance setup was nearly instantaneous, letting me focus on my neural architecture search rather than server orchestration.

Unrivaled Cluster Stability
Enterprise Success

Unrivaled Cluster Stability

Dr. Elena Vance, CTO at Nexus Generative Labs

The H100 performance on IPX GPU is the gold standard; we achieved 98% linear scaling across our 512-node cluster without a single interconnect bottleneck. Their technical support team operates with a deep understanding of the NVIDIA stack, providing immediate, expert-level resolution for complex InfiniBand optimizations.

Built for Performance

The Infrastructure Powering Next-Gen AI

Engineered in Delaware to provide the reliability and speed that high-level ML researchers demand for large-scale model training.

Direct-to-Chip Architecture
Zero Overhead

Direct-to-Chip Architecture

Maximum TFLOPS Utilization

We eliminate the virtualization layer to ensure your training jobs have direct access to the silicon. IPX GPU's custom-tuned kernel bypasses traditional bottlenecks, delivering raw compute power straight to your PyTorch and TensorFlow workloads.

Ultra-Fast InfiniBand Fabric
Low Latency

Ultra-Fast InfiniBand Fabric

Multi-Node Scaling

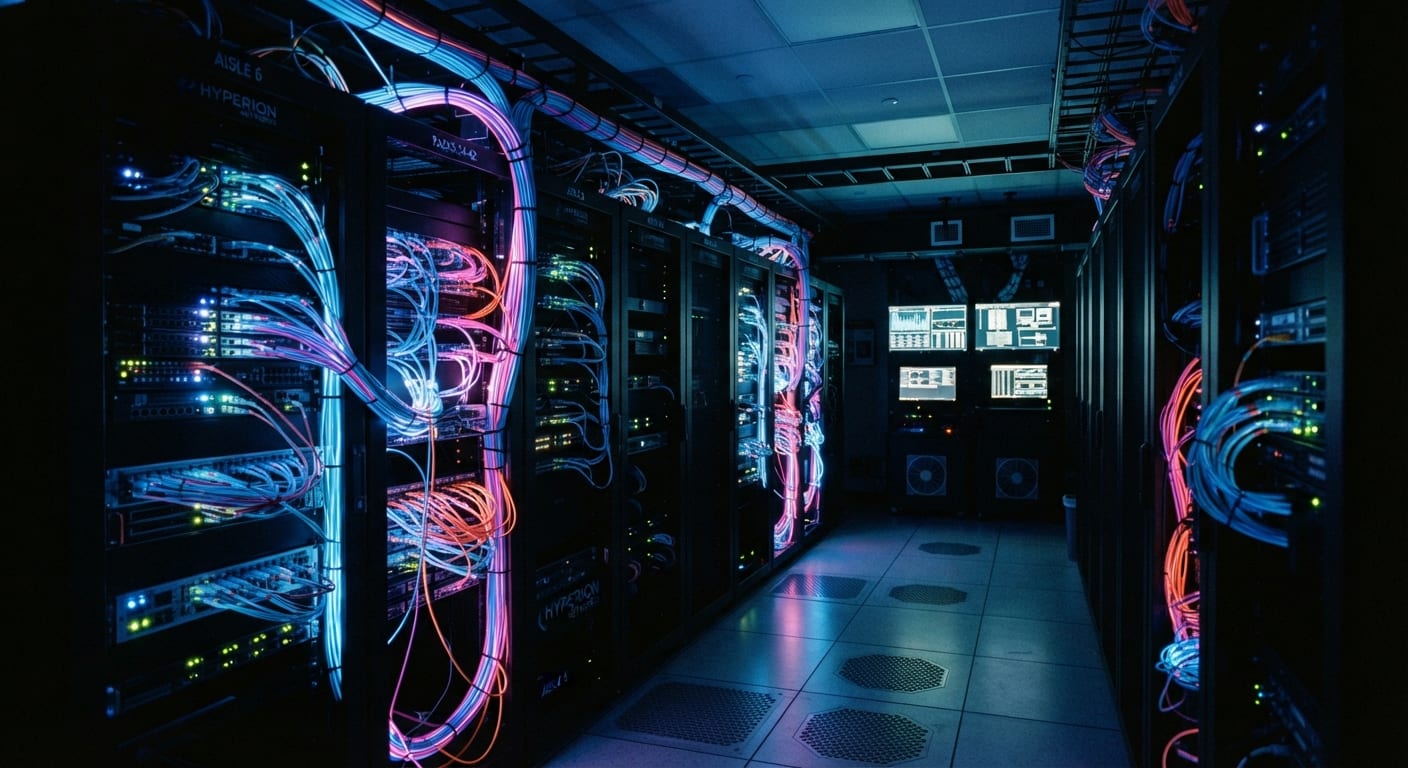
Scale your models across dozens of nodes without hitting a communication wall. Our 400Gbps NDR InfiniBand interconnect ensures that data movement between GPUs happens at lightning speed, minimizing synchronization overhead for distributed training.

Advanced Liquid Cooling Systems
Sustained Peak

Advanced Liquid Cooling Systems

24/7 Stability at 100% Load

Long-running training sessions require thermal consistency to prevent hardware throttling. Our engineering team has implemented custom-designed liquid cooling loops that maintain optimal temperatures even during the most intensive 100% duty cycles.

Optimized ML Software Stack
Ready to Run

Optimized ML Software Stack

Pre-Configured Environments

Spend less time configuring drivers and more time iterating on your architecture. Every IPX GPU instance comes pre-loaded with the latest CUDA drivers, cuDNN libraries, and container runtimes optimized for our specific hardware profiles.

Connect with IPX GPU

Scale Your Neural Networks with Precision Support

Whether you are troubleshooting a complex training run or securing bulk compute credits for a research lab, our team is ready to assist.

Wilmington Operations Center
Corporate HQ

Wilmington Operations Center

Wilmington, Delaware, USA

Our central hub manages global credit allocations and infrastructure logistics for researchers across North America. Visit us or reach out for inquiries regarding institutional billing and large-scale enterprise credit agreements.

Technical Support Desk
24/7 Engineering

Technical Support Desk

Global Infrastructure Support

Dedicated to maintaining 99.9% uptime for your AI/ML workloads. Our engineering team provides specialized assistance for GPU driver configurations, cluster management, and optimizing resource utilization for high-demand training cycles.

Research & Sales Team
Partnerships

Research & Sales Team

Custom Compute Solutions

Specifically tailored for AI labs and independent researchers looking for high-density compute power. Contact our sales specialists to discuss reserved instance pricing, multi-node scaling, and custom GPU credit packages designed for long-term projects.

Ready to Train Your Next Model?

Get started with $50 in free compute credits today.